---
title: "Seven Hundred Commits to Teach a Reviewer It Was Wrong"
audience: [lead, build]
level: deep
subtitle: "In August I wrote one Claude skill to review pull requests in my voice. Three months later it runs on a schedule, borrows Codex when Claude runs dry, builds on teammates' reviews, and most of its commits are the reviewer being corrected."
author: "Tjakoen Stolk"
status: PUBLISHED
type: note
layout: timeline
date: 2026-11-09
readingTime: "~12 min"
tags: [ai, leadership]
people: [kaither-holiway, kercwin, addy-osmani]
sources: [book-loop-engineering]
summary: >
The story of my PR review kit at Career Team, told from its git history: one hand-run Claude skill
in August, a talk that introduced it to the team in September, then an outcome log that scores
every finding, misses replayed at the commit they slipped through, routines that answer their own
threads, a kit other managers install, Codex as a backup, risk intake and an epic check, and the one
production break it let through. It got
good by being measured against its misses, not by being prompted harder, approval never left my hands, and
the hours it gave back went to my team.
social: |
I was still reading every word my AI code reviewer wrote. In a manager meeting I told our Director
of Engineering, Kaither Holiway (https://www.linkedin.com/in/kaither-holiway/), that I didn't trust
it.
He asked, "Why not?"
I didn't have a good answer, so I spent three months and seven hundred commits earning one. The
reviewer now grades every comment it leaves by what happened next, and when it misses something, the
fix gets replayed on the exact commit it missed.
One in four of my team's pull requests used to wait 17 hours or more for a first review. Now that
one in four waits 3 hours or more.
It also gave me my time back. The hours I used to spend on first-pass review now go to the people
on my team instead of the queue.
Thank you, Kaither, for the question that inspired all of it.
socialImage:
- "/media/notes/the-reviewer-that-learned-to-be-wrong-social-1-question.png"
- "/media/notes/the-reviewer-that-learned-to-be-wrong-social-2-loop.png"
- "/media/notes/the-reviewer-that-learned-to-be-wrong-social-3-wait.png"
- "/media/notes/the-reviewer-that-learned-to-be-wrong-social-4-board.png"
socialImageAlt:
- "The question that started it, set large: \"I don't trust it.\" and \"Why not?\", with the answer three months later: I don't re-read its reviews any more."
- "How the reviewer learns: a review comment stamped FIXED and WRONG, with arrows around it. The lens that missed gets fixed, then replayed on the commit it missed. Every miss becomes a test it has to pass next time."
- "Two bars for how long 1 in 4 of the team's pull requests waited for a first review: 17.6 hours before the reviewer, 3.0 hours now, with cost per review down by half."
- "Card four of four: the real review board on invented pull requests, in columns for queued, in flight and waiting on author, under the line: it reviews my team's pull requests on its own. Approval still stays with me."
---
My PR review kit is a set of Claude skills that reviews my team's pull requests at [Career Team](/leading) the
way I would, in the tone I would, and posts under my account. It reads the ticket before the diff,
it never approves anything, and it keeps a log of every time it was wrong. That last part is most of
the story.
On `Aug 14` I committed the first version of a skill called `/check-pr-voice`. The next day I made forty more
commits to it, and one of them was titled `feat(check-pr): review the ticket, not just the diff`. That should have
told me how this was going to go. As a snapshot, on `Nov 9` the repository has 737 commits and
sits at release 2.6. The number sounds like a flex and it is closer to a confession: most of those
commits are the reviewer being told it was wrong, and me building the machinery to tell it.
> **Every screen in this note runs on mock data.** The board is the real one, running on invented pull
> requests and invented people. The real version holds Career Team's work, and it stays at work. I am
> careful about that line, so this note shows how the kit works and how it got there, never what it
> found.
### The turns, on one line
## Early Aug · Why not?
Before any of this I was already using the company's standard PR reviewer, and I was still reading
every word it wrote. My name goes on the approval, so its output had to be right before I clicked
anything. I also sit in the architecture group, which means some pull requests cannot merge until I
review them, and that summer, code review was a real bottleneck on the team. Architecture review
was the worst of it, and a fair share of that queue was waiting on me.
So in a manager meeting I raised it with [Kaither Holiway](/people#kaither-holiway),
our Director of Engineering. Before Career Team he was a Senior Software Engineering Manager at
GoFundMe, where by his account the engineering teams went hard on AI and built it into how they
actually worked, and that was the bar he wanted to bring here. I explained that I was still
checking everything the reviewer did by hand. He asked why. I said I did not trust it.
He asked, "Why not?"
Something clicked. I did not have a good answer, and I realized the honest response was not to keep
distrusting the reviewer but to make it into something I could trust. Then came the rabbit hole.
The first thing I noticed was how much there was to learn from other people's reviews. The
architecture group takes review seriously and leaves a lot of feedback, so before I changed a line
of the reviewer I pulled hundreds of their reviews and mined them for the rules they kept repeating.
That turned into the self-learning loop the rest of this note is about: the reviewer's own comments
scored against what happened next, and every miss folded back in as a lesson.
From there it spread outward, and it turned into a habit. Whenever someone shares something I think
could make the reviewer better, a teammate's tool, a post, a paper, I take what I can from it and
put it in the kit. I read how other reviewers work and kept reading as new things came
out. When I saw how Google writes down its standard for code review, how Alibaba moved the parts of
its AI reviewer that must not go wrong out of the model and into plain code, and how [Addy Osmani](/people#addy-osmani)
describes the loop that agentic work runs on, each one went into the kit. The full list is in the
sources at the end.
What Kaither gave me in that meeting was a question. It made me want to trust my AI, and trust it
for reasons I could show rather than a feeling. Everything below is me trying to earn that:
a record I could check, a fix every time the record said it was wrong, and guardrails around the
parts I was never going to hand over.
## Aug 14 · It started as a reviewer I had to babysit
The first version was a skill I typed a pull request number into and watched. I started from the
staff-level PR reviewer Kaither built for Career Team's platform group. The core was his: a handful
of parallel lenses over the change (security, accessibility, tests, migrations, a staff-engineer
read), every finding checked a second time before
it was kept, and one review posted with comments anchored to lines. What I added was the reading
before the diff, the linked ticket and its epic, and my own tone on the way out. Then it waited for
me to run it again. Theirs is the reviewer for everyone. Mine is the opinionated one, and it
reviews the way I do.
The first two days of history are mostly the skill learning manners. The commit titles read like
notes from a bad first week:
```console
$ git log --reverse --format='%ad %s' --date=short
2026-08-15 feat(check-pr): review the ticket, not just the diff
2026-08-15 feat(check-pr): post one review, and stop calling everything Minor
2026-08-15 feat(check-pr): ask whether we already built this
2026-08-15 feat(check-pr): scale the review to the diff, but never by size alone
...
```
Each of those is a review I watched go out and winced at. It was useful from
day one and annoying from day one, which I suspect is true of most first hires.
## Aug 18 · Then it had to keep score
On `Aug 18` the history gets `fix(check-pr): the first scored outcomes, and the one lesson in
them`, and it is the turn the rest of the story hangs on.
Every finding the reviewer posts gets a row in an outcome log, scored later by what happened to it:
fixed, answered, closed without a change, or ignored. Anything a human reviewer caught that mine did
not goes into a separate miss log. By `Sep 9` there was a standing skill, `/calibrate-pr-voice`,
whose only job is to read those logs and fold the lessons back into the lenses.
I would love to say this went smoothly. On `Oct 1` there is `calibrate: lock the outcome log,
because eleven scores in twelve were being lost`. Two routines had been writing to the same file and
quietly overwriting each other, so for a stretch the reviewer was being graded on a sample of almost
nothing and I had not noticed. A measuring tool that loses its measurements is a very confident way
to learn nothing.
> A reviewer does not get better by being prompted harder. It gets better by being shown, row by
> row, where it was wrong.
This is the part of the kit I care about most, and the part I would build first if I started again.
The reviewer is not a prompt I keep polishing. It is a loop that grades itself and changes itself,
and I sit at one point in it. This is the loop from the talk:
Two details in that loop do most of the work. Every score is read per topic, never as one average,
because a reviewer can be excellent on database changes and noisy on frontend speed, and the mean of
those looks fine. And the heavy bar on the arrow into a change is me. The loop can find the lens that
needs fixing and propose the fix, but it cannot change itself without my sign-off, and every change
it does make is re-run on old pull requests before it counts.
## Sep 17 · The talk was the old version
On `Sep 17` I introduced the kit to the team in a talk, [Every Time It Was
Wrong](/talks/every-time-it-was-wrong). By then it was not a reviewer I ran by hand any more. It was
already largely automatic and already learning from itself. It ran out of the Claude Code desktop
app: scheduled checks found pull requests waiting for review, spun up a session for each one, and
filed every session into a sidebar section by its status, so the sidebar itself was the board. The
same day I moved the board off the tool I had started it in and onto that sidebar for good.
The deck is still up, and its diagrams are the clearest picture of how the reviewer thinks, so two
of them are in this note. This is the review as the talk showed it. Six specialist reviewers read
the change at once, and most of what they find never reaches the author:
That shape has not changed since.
The same days in the history are the densest of the early stretch. A second skill,
`/respond-pr-voice`, started answering replies waiting on us, checking a claimed fix at the new
commit, resolving its own threads and updating the verdict label. A push from the author started
queueing a re-review, an incremental pass over the new commits, instead of a whole new review. Every
unattended routine got one report format, so I could read a night's work in a table instead of a
transcript.
## Sep 28 · Then other people wanted it
On `Sep 24` the repository was restructured so someone who was not me could clone it, and on
`Sep 28` the installer learned to set the kit up from a profile per person. Everything personal,
the outcome log, the watcher state, the boards a person cares about, moved under that person's own
directory.
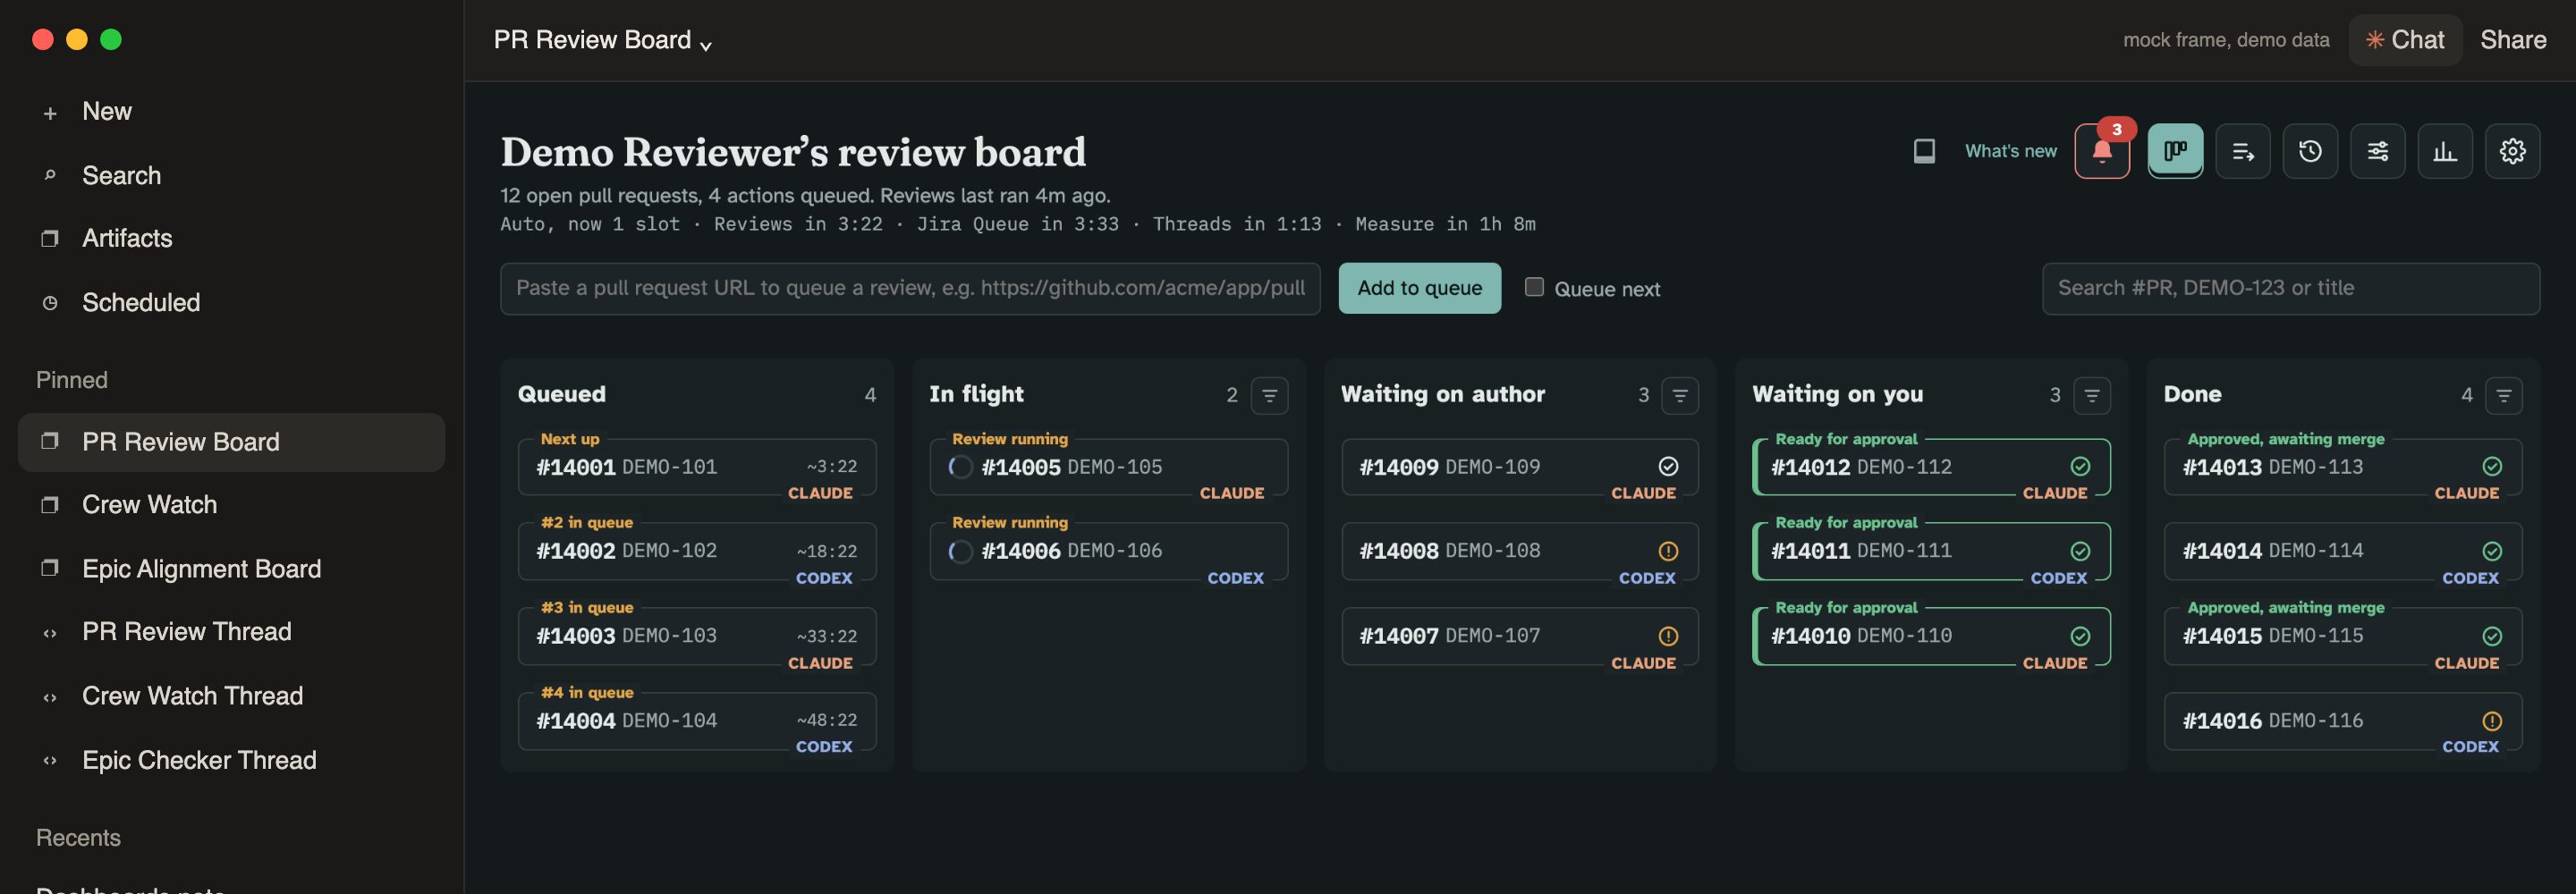
The board page followed on `Oct 14` and 15: one page per person with Board, History, Calibration and
Stats tabs, cards that move between columns depending on who owes the next move, a Run now button,
settings that live on the board, and setup from one paste. The 1.0 release notes put it plainly:
the first release a teammate can set up, use and repair alone. I am no longer the only manager whose
reviews run through it.
The board as it looks today, running on invented pull requests. No card here is a real one.
Once there were two kits, they started reviewing the same pull requests. On `Oct 19` the kit
learned the second look: when a teammate's kit has already reviewed the head commit, mine runs only
what theirs left unchecked, posts an addendum. At first it left a one-line note when it had nothing new; now it posts nothing
at all.
Since `Nov 4` every second look carries its own label, so a silent one still shows on the pull
request. In November my kit also started taking a second look when the platform group's reviewer
had already left a verdict. It builds on that review instead of repeating it.
## Oct 8 · Then it needed a second engine
There is a practical problem with running a reviewer on a schedule, which is that my Claude usage is
finite and pull requests are not. On `Oct 8` the reviewer was installed and adapted for Codex, and
by `Oct 11` the calibration loop found reviews from both hosts through their attribution labels,
so a review Codex wrote is scored in the same log as one Claude wrote.
Then it became the fallback for when I run low on tokens. On `Oct 15` the switch stopped being
something I flipped by hand, and on `Oct 20` and `Oct 21` it got finer. As my weekly Claude use climbs, the kit runs fewer reviews at
once, and past a threshold I choose it hands them to Codex:
| Weekly Claude use | Claude reviews at once |
|---|---|
| Under 70 percent | Four |
| 70 percent | Three |
| 80 percent | Two |
| 90 percent | One |
| Past my threshold | New reviews go to Codex |
A pull request keeps the engine that first reviewed it, so a conversation that
started with Codex finishes with Codex instead of changing voice halfway through.
That still left the week I burn through Claude completely, when the board itself has nothing to run
on. So I built a second, much smaller thing next to the kit: a minimal Codex dashboard that shows
the review queue and lets me keep reviews moving with no Claude at all. It is plain on purpose. It
exists for the bad week, and on the bad week I want a list and a button, not a tour.
Codex is the backup, not a peer I benchmark against in this note. The comparison work exists in the
plans folder and it is not finished. What is finished is that a quiet week on one engine no longer
means a quiet week on reviews.
## Oct 13 · Then it had to earn its keep
A reviewer that runs every night has a bill, and I wanted model choices made the same way as lens
changes: on results, not on taste. So the model behind each part of the kit is a decision with a
trial behind it.
| What runs it | What I tried | What the results said |
|---|---|---|
| The six lenses and the skeptic | Pinned to Sonnet in September | They held their precision, so the expensive model only does the parts that need judgment |
| The review itself | Opus 5 at medium, then Opus 5.5 at medium, and now Opus 5.5 at low | Low held up: across thirty reviews it found more per review than the medium baseline, and not one blocking finding was thrown out |
| The routines that only check for work | Haiku | Far cheaper per check, but a pinned model does not switch a session that is already running, so the slots went back to Opus |
On `Oct 13` the kit started pricing every review session, lens agents included, at list rates for the
model each turn ran on. That is an estimate rather than the bill, but it is the same estimate every
week, so the trend is real. The board's Stats tab plots it, and over the four weeks the first data covered, the median cost of a review fell by more
than half. Trial four, a stricter low setting, is still running.
## Oct 14 · Then it had to prove its repairs held
A replay ledger arrived on `Oct 14`, and by mid-October it did the part that convinced me: when a lens
gets repaired after a miss, the repair is replayed on the pull request the miss came from, at the
commit the original review ran on. On `Nov 3` a batch of thirty-three replays came back and nine
lens rules were fixed because the replays found them wanting. A repair that has not been replayed is
a hope. A replayed one is a receipt.
## Oct 18 · Then it got a map of the code
The lenses I started from read the diff and the files around it. That is the company reviewer's
shape, and it misses the thing that breaks most often in a codebase our size: the code that is not in
the diff but depends on it. So on `Oct 18` the kit gained code graphs, built with
[Graphify](https://github.com/Graphify-Labs/graphify) from each branch the team ships, and shared by
everyone who runs the kit.
Before the lenses run, the review cuts a slice of that graph for the change and hands it over:
- who calls each changed function,
- functions with the same name in other apps,
- the permission and feature gates on each one,
- and the tests that touch them.
The graph is rebuilt whenever its branch moves. It also does a second job I did not
plan for. Risk intake asks the same graph whether an outside pull request reaches code my team owns,
and uses it to ignore the shared helpers that almost everything touches, which would otherwise make
every change look like ours.
This is company code, so Graphify gets the same treatment as everything else in the kit that touches
it: hard blocks, not good intentions. It is an outside library, and the kit runs only its code-reading
pass, as a pinned version checked against a hash, in a sandbox with no network. Its installers, hooks
and server are never run. The graphs it produces stay in the kit's private repository and on the
machines of the people who run the kit. A tool that reads the whole codebase cannot send any of it
anywhere, because nothing in that sandbox can reach anywhere to send it.
The honest limit: the graph slice is still on a watch rather than on for everyone. It runs on my
reviews while I measure whether the lenses that get it find more than the ones that do not.
## Oct 26 · Then it had to decide what deserved a look
The newest turns are the reviewer getting choosier about its inputs. On `Oct 26` it started
reading the epic's decided rules and the decisions made in Jira comments, and on `Nov 3` it folded
in the [epic check](move-bugs-left.md) that
[Kercwin](/people#kercwin), a tech lead on my team, built as
his own plugin after seeing my board (the story is in
[I Showed My Team a Dashboard](show-them-the-board.md#kercwins-epic-checker)), so a deviation the team already agreed to
stops being flagged as a defect. The same day risk intake arrived: a pull request from outside my
boards gets queued only when it touches a high-risk area and reaches code my team owns, capped at a
ranked three a day so the queue does not drown.
Release 2.6, on `Nov 4`, made every lens prove it read its rules before its findings count. A
lens that skips them twice gets named in the evidence block, and the review cannot post PASS. Show your work, or it does not
count.
## Oct 30 · Then it let one through
I have run the kit unattended for months, and in that time we broke production once on a change it
had passed. A data-fix migration was meant to remove a few unwanted entries from one customer's
dropdown. Its filter matched on a type field that some unrelated rows also carried, so it switched
off a handful of reference rows another part of the product depended on. The rows were switched off,
not deleted, so nothing was lost, and they were restored from the backup the migration itself had
taken. But for a few weeks some staff could not record work they needed to record, and nothing on
screen told them why.
The reviewer had read that migration and said nothing. So it went through the same loop as every
other miss, with more at stake. It was recorded against the migrations lens, and on `Oct 30` that lens
got a new rule: a change to rows that other features read is checked against every reader of that
data, not just against the ticket that asked for it. Then the repair was replayed on the original
pull request, at the commit the review had read the first time, with no hint of what had gone wrong.
It blocked the change. Two other pull requests with the same shape went in as test cases alongside it, and it caught
those too.
One production break in months is a record I am comfortable defending. It is also the best argument
for the loop I have. A reviewer that never misses does not exist, so the question was always what
happens after the miss.
## Nov 9 · How it works now
A pull request lands on my board from my team's code review column, from risk intake, or because I
pasted it in. Scheduled routines take it from there, and only between 17:00 and 06:59. That is my
working day, since I work nights, so every review lands while I am awake to answer for it.
The loop at the center is the one I showed in September. Reviewing, following up and learning from
every outcome were all running by the talk. What changed since is everything around that loop:
where pull requests come from, what a review reads before the diff, who else is reviewing, and which
engine does the work. The dates below say which is which.
**The review.** A Reviews routine works through the same steps every time:
- It reads the ticket and its epic before the diff. Since `Aug 15`.
- It sends six specialist lenses over the diff and tries to refute every finding before keeping it,
then posts line-anchored comments with a PASS, REQUEST CHANGES or BLOCKING verdict. Since the
first version, and on the September slides.
- It checks the change against the epic's decided rules and the decisions in the ticket's comments,
and notes any other open pull request editing the same lines. Since `Oct 26`.
- It runs the epic check where the epic has one. Since `Nov 3`.
**After the review.** Each event that follows gets its own response:
| When this happens | The kit does this | Since |
|---|---|---|
| An author replies to a thread | Answers it if the team's recorded decisions settle it, otherwise leaves it for me | `Sep 16` |
| An author says it is fixed | Checks the fix at the new commit and resolves its own thread | `Sep 16` |
| An author pushes new commits | Runs a re-review over just those commits | `Sep 17` |
| A teammate's kit already reviewed the head | Runs a second look over only what theirs left unchecked | `Oct 19` |
| My Claude use passes the weekly threshold | Hands new reviews to Codex | `Oct 15` |
**The learning half.** This is the part that earns the trust, and most of it predates the talk:
- Every comment is scored by what happened next. Since `Aug 18`.
- Every miss is recorded with the lens that should have caught it. Since `Aug 19`.
- A theme that keeps being closed without a fix gets its lens tightened. Since `Sep 9`.
- Every repair is replayed on the pull request where the miss happened, at the commit the review ran
on. Since mid-October, and the one big addition to the loop after the talk.
The Calibration tab shows each change to the reviewer and why it was made.
It never approves, never merges and never pushes code. Guards block a push rather than merely
discourage one. A PASS from the kit means it has nothing left to say, and the approve button stays
mine.
## What the team felt, and what I got back
The bottleneck that started all this was review wait, so that is the number I checked. Crew Watch,
the team dashboard I built for my one-on-ones and wrote about in
[I Showed My Team a Dashboard](show-them-the-board.md), keeps every pull request my team opened since late
July with its reviews. This is the time from a pull request being opened to its first review by
anyone other than its author, as a snapshot on `Nov 10`:
| Pull requests opened | Reviewed | Median wait | 1 in 4 waited longer than |
|---|---|---|---|
| Before `Aug 14`, no kit | 53 | 1.7 hours | 17.6 hours |
| `Aug 14` to `Sep 16`, run by hand then on routines | 87 | 1.5 hours | 12.6 hours |
| `Sep 17` to `Oct 14`, automatic on the sidebar | 81 | 1.7 hours | 13.2 hours |
| `Oct 15` to `Nov 10`, the board and Codex as backup | 98 | 0.9 hours | 3.0 hours |
The median barely moved, because most pull requests were never the problem: someone usually picked
them up within a couple of hours. The long tail is what the kit took apart. One pull request in
four used to wait most of a day or more. Since the board and the Codex fallback, that one in four
waits three hours or more. That is
the bottleneck I raised in that manager meeting.
The honest limits on that table: these are wall-clock hours, nights included, so an overnight
routine flatters itself against a human who reviews in the morning. The window before the kit is
only a few weeks, and other things changed over the same months that I cannot separate from the
kit. It is a before and after, not an experiment.
The other half of the payoff was mine. Before the kit, first-pass review ate a big share of my
working hours. I was the bottleneck, reading every word a reviewer I did not trust had written. Now I
do not re-read its reviews at all. I trust them, which was the whole point of answering Kaither's
question, and the calibration that earned that trust runs without me. So the hours that used to go
to the review queue go to the people on my team instead: the one-on-ones, the unblocking, the
dashboards I wrote about in [I Showed My Team a Dashboard](show-them-the-board.md). For a manager,
that is the real trade. The kit took the part of the job a machine can be held to a standard on, and
gave back the part only I can do.
## What I have not shown
I have not shown that the kit makes the codebase better. I have shown that its findings get scored,
that its misses get replayed, and that the share of its comments people act on is something I can
look at instead of guess at. Whether that adds up to fewer bugs reaching production is a longer
study than three months, and I have not run it.
Back to that commit on day two, `feat(check-pr): review the ticket, not just the diff`. Seven hundred commits later
the kit still does that first, and almost everything after it is the same idea, applied to the
reviewer itself: read what it was supposed to do, then check what it actually did.
## Sources
Almost nothing in the kit was designed from scratch. Most of it was extracted, and the kit keeps its
own credits file so every rule can be traced. The parts that shaped the system, as opposed to a
single rule:
**Inside Career Team**
- My colleagues' review comments. The kit's standards are mined from real reviews on our codebase,
and a rule earns its place when the team's own reviewers said the same thing more than once. The
times a person caught what the reviewer missed are worth the most, since each one became a gate, a
standard or a test case.
- The platform group's Claude plugins: Kaither's staff-level PR reviewer, whose lenses and verification step the kit
started from, and the PR
fixer whose evaluation suite taught me to test whether a review is any good, not only whether the
machinery runs.
- Kercwin's epic check, which supplies the epic decisions and the collision check, and which
the kit runs as a plugin since `Nov 3`. How he came to build it is in
[I Showed My Team a Dashboard](show-them-the-board.md#kercwins-epic-checker).
**Published work**
- Addy Osmani, [Loop Engineering](https://addyosmani.com/blog/loop-engineering/), for the shape of
the loop, and his writing on code review becoming the bottleneck once code arrives fast.
- Google's [The Standard of Code Review](https://google.github.io/eng-practices/review/reviewer/standard.md),
for continuous improvement over perfection, and for polish as an ignorable nit.
- Sadowski and colleagues, [Modern Code Review: A Case Study at
Google](https://research.google/pubs/modern-code-review-a-case-study-at-google/), and Bacchelli
and Bird, [Expectations, Outcomes, and Challenges of Modern Code
Review](https://www.microsoft.com/en-us/research/publication/expectations-outcomes-and-challenges-of-modern-code-review/).
Both also mark the one place the kit disagrees with the literature on purpose: it cuts most of the
code-improvement comments those papers say human review earns its value on, and trades them for
precision.
- The Cisco and SmartBear review study, for the evidence that coverage falls as a change grows. Its
numbers measure human fatigue, so the kit borrows the shape and not the threshold.
- [alibaba/open-code-review](https://github.com/alibaba/open-code-review), for moving every step
that must not go wrong out of the model and into plain engineering.
- [Conventional Comments](https://conventionalcomments.org/), for every comment label the kit posts
and the rule that a reader should never have to guess whether feedback blocks the merge.
- Anthropic's model migration guidance, the premise of the kit's effort trials.
- [Graphify](https://github.com/Graphify-Labs/graphify), which builds the code graphs the lenses
read and risk intake uses to tell which code is my team's.
**My own notes**
- [The Check Ran Once in 165 Sessions](the-check-that-never-ran.md), for distrusting a check that
reports success while looking at nothing.
- [Watch Its Hands](watch-its-hands.md), for verifying what an agent did rather than what it says.
- [I Was Shipping Faster Than I Could Understand It](one-loop-every-repo.md), for one loop per repo.
- [VOICE](https://portfolio.tjakoen.com/standards/voice), the writing standard every posted comment
is held to.
---
*The [judgment is human](ten-times-zero.md). The typing, by design, is not.*